Engineering · 2026.10.03 · 5 min · Updated 2026.10.26
Catching Dependency Cycles in Rust and TypeScript: A Homemade Module Scanner With Layering Rules in CI
My 18 backend packages had several dependency cycles tracked only by memory, so I wrote a compile-free scanner for a clickable architecture map and CI layering rules, then cleared 23 violations in one day.
Reading
My Rust backend's 18 packages had several dependency cycles, lending and subscription depending on each other for example, and the repo had no dependency rules at all. Memory was the only thing keeping track.
What I ended up with is a scanner I wrote myself that reads the source without compiling anything. It covers both the Rust backend and the TypeScript frontend, and its rules run in CI.
With the layers ordered to match the existing code, there were only 23 violations, and I cleared all of them the same day. Only 2 actually needed dependency injection.
It started because I wanted an architecture map I could click through from a layered overview down into submodules, then into the code itself, with a clear definition of which modules may depend on which.
Existing tools don't connect
I looked at cargo-modules, dependency-cruiser, and ESLint's boundaries rules.
Each one covers only one side of the stack, their rule formats don't connect to a map, and the backend tool needs a compile first.
So I wrote a tool that uses nothing but Node's built-in modules. For Rust it recognizes paths like crate:: and super::, plus access through State. For TypeScript it recognizes import, export … from, and import().
The whole check takes about half a second.
The map is a single HTML file with roughly 9 MB of embedded source, and it stays out of version control. It's derived from the source, and committing it would add a 9 MB diff to every PR.
The rule: depend only downward
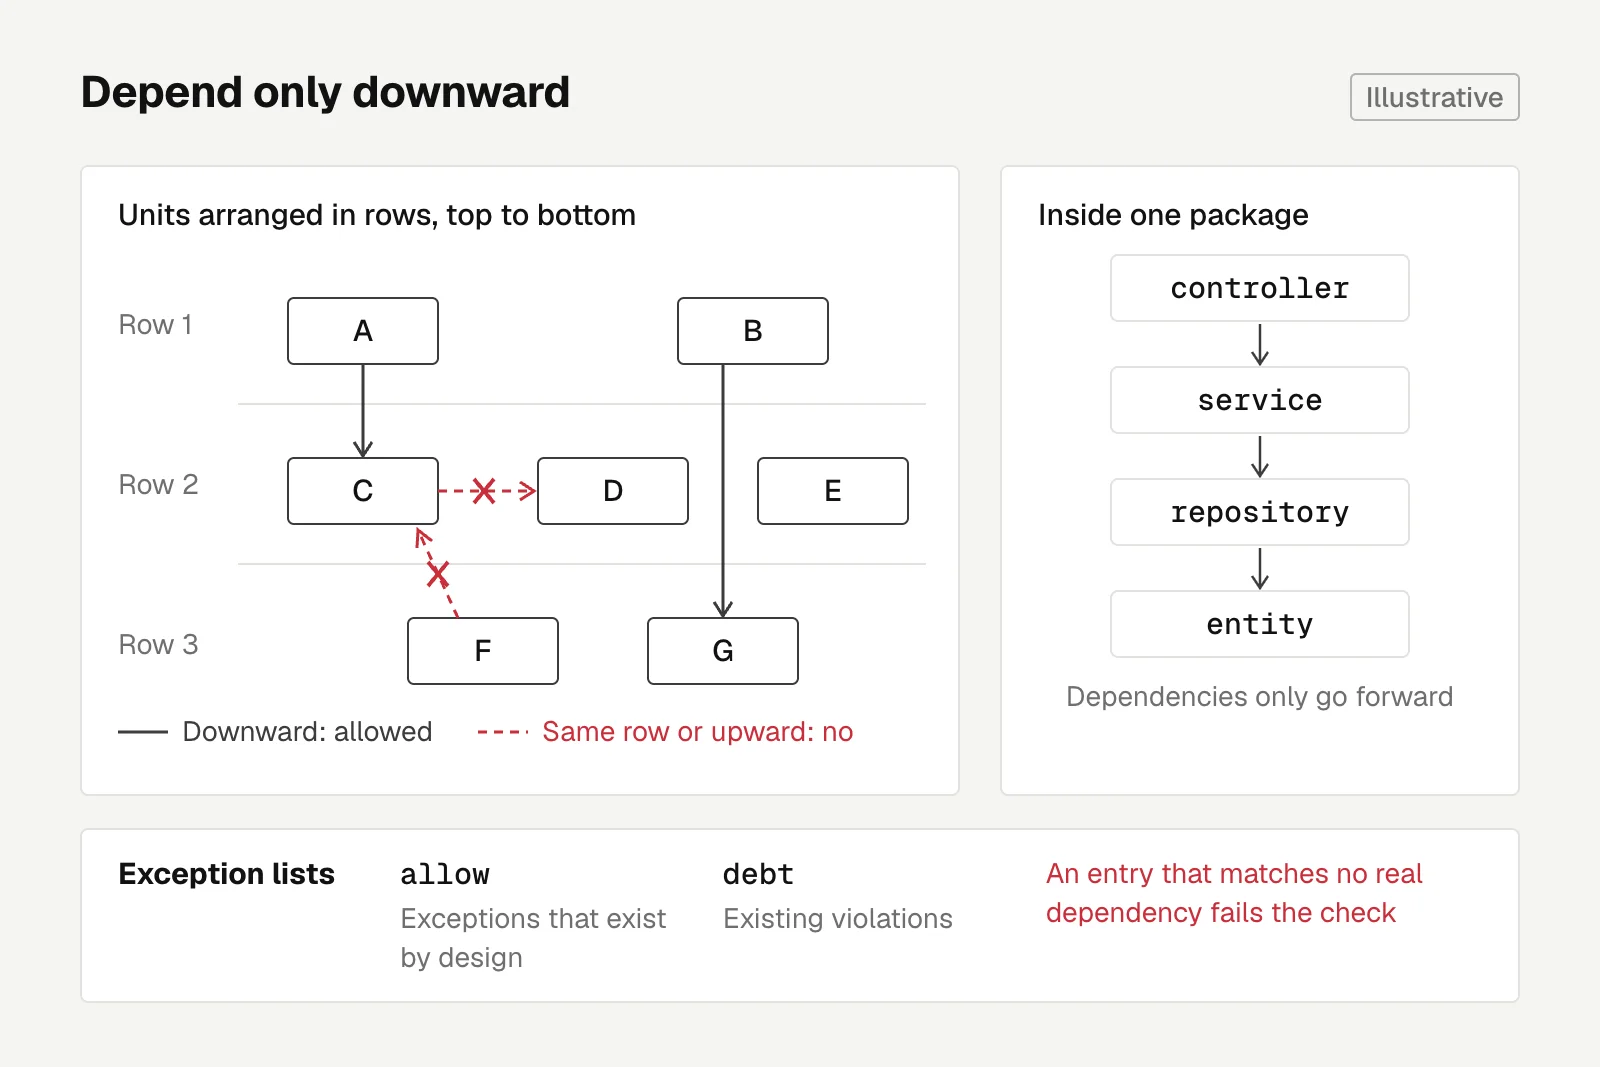
Units are arranged in rows from top to bottom, and a unit may only depend on units in the rows below it. Units in the same row can't depend on each other, and nothing depends upward.
Inside a single package there's one more rule: controller → service → repository → entity, and dependencies only go forward along that chain.
Exceptions live in two lists. allow holds exceptions that exist by design, and debt holds existing violations.
If any entry in either list doesn't match a real dependency, the check fails. When a dependency gets removed and the list isn't updated, CI flags it, so the lists never pile up stale entries.
Backend CI gets one extra check step, and the frontend check hooks into npm run lint. A new reverse dependency gets blocked at the PR.
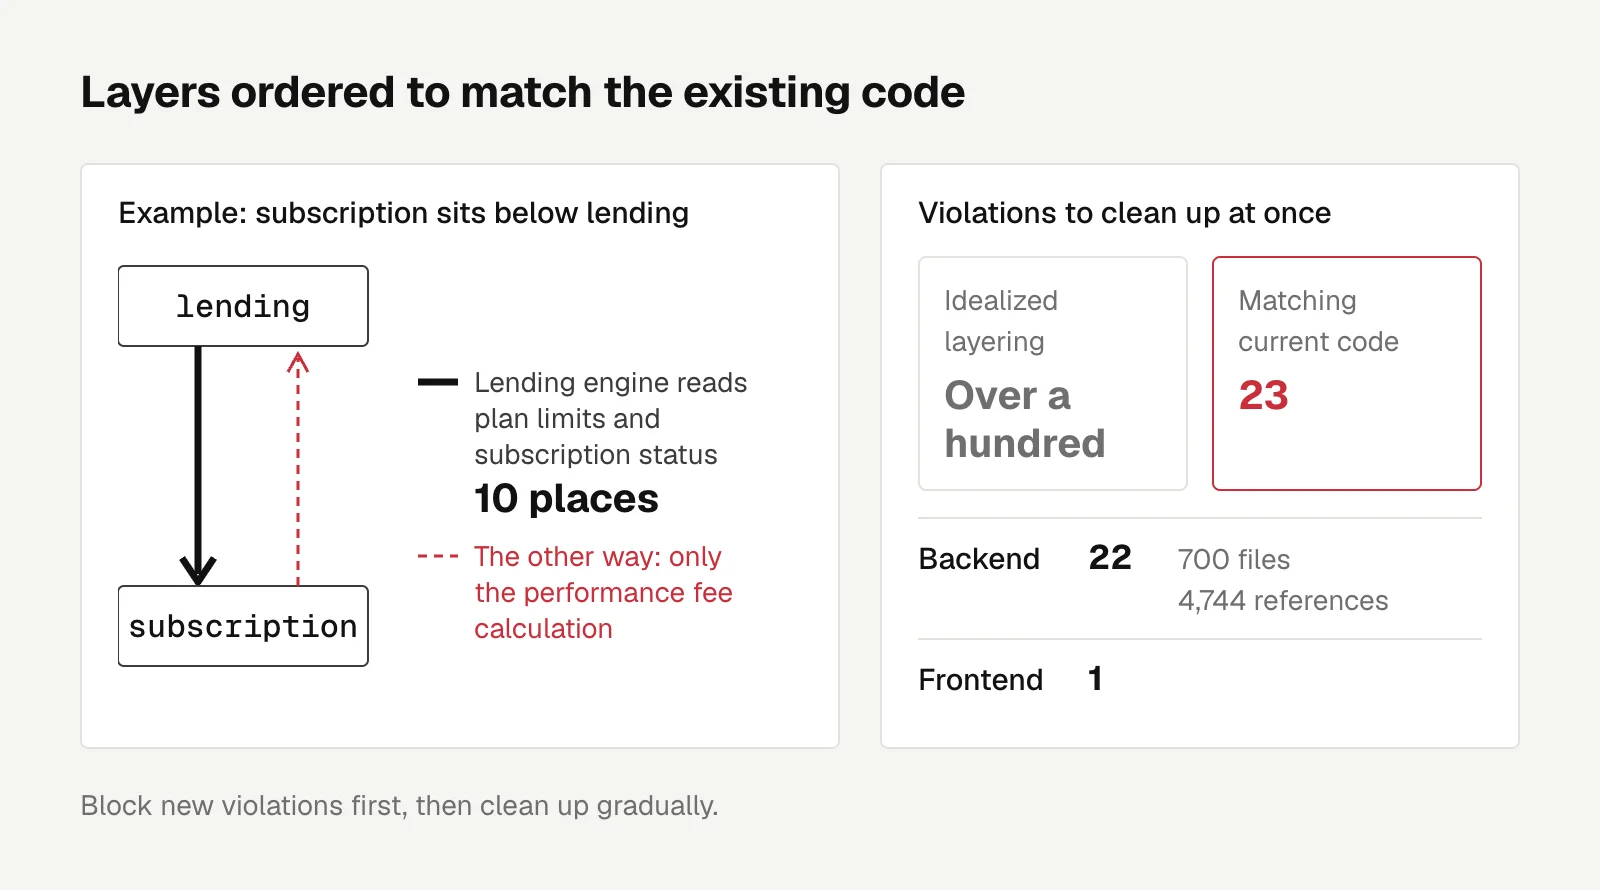
Layers ordered to match the code
An idealized layering would have produced over a hundred violations to clean up at once, a list so long nobody would read it.
So I ordered the layers to match the current code, picking the order with the fewest violations. Block new violations first, then clean up gradually.
For example, subscription sits below lending, because the lending engine reads plan limits and subscription status in 10 places. The only thing going the other way is the performance fee calculation reading lending data.
With that ordering, the backend's 700 files and 4,744 references had only 22 violations, and the frontend had 1. The layering roughly matches the existing code, and the cycles are concentrated in a handful of files.
The layer order was sorted by an agent based on violation counts, and I haven't reviewed it entry by entry. If I disagree with something later, I just edit the rules file.
23 violations, mostly moved files
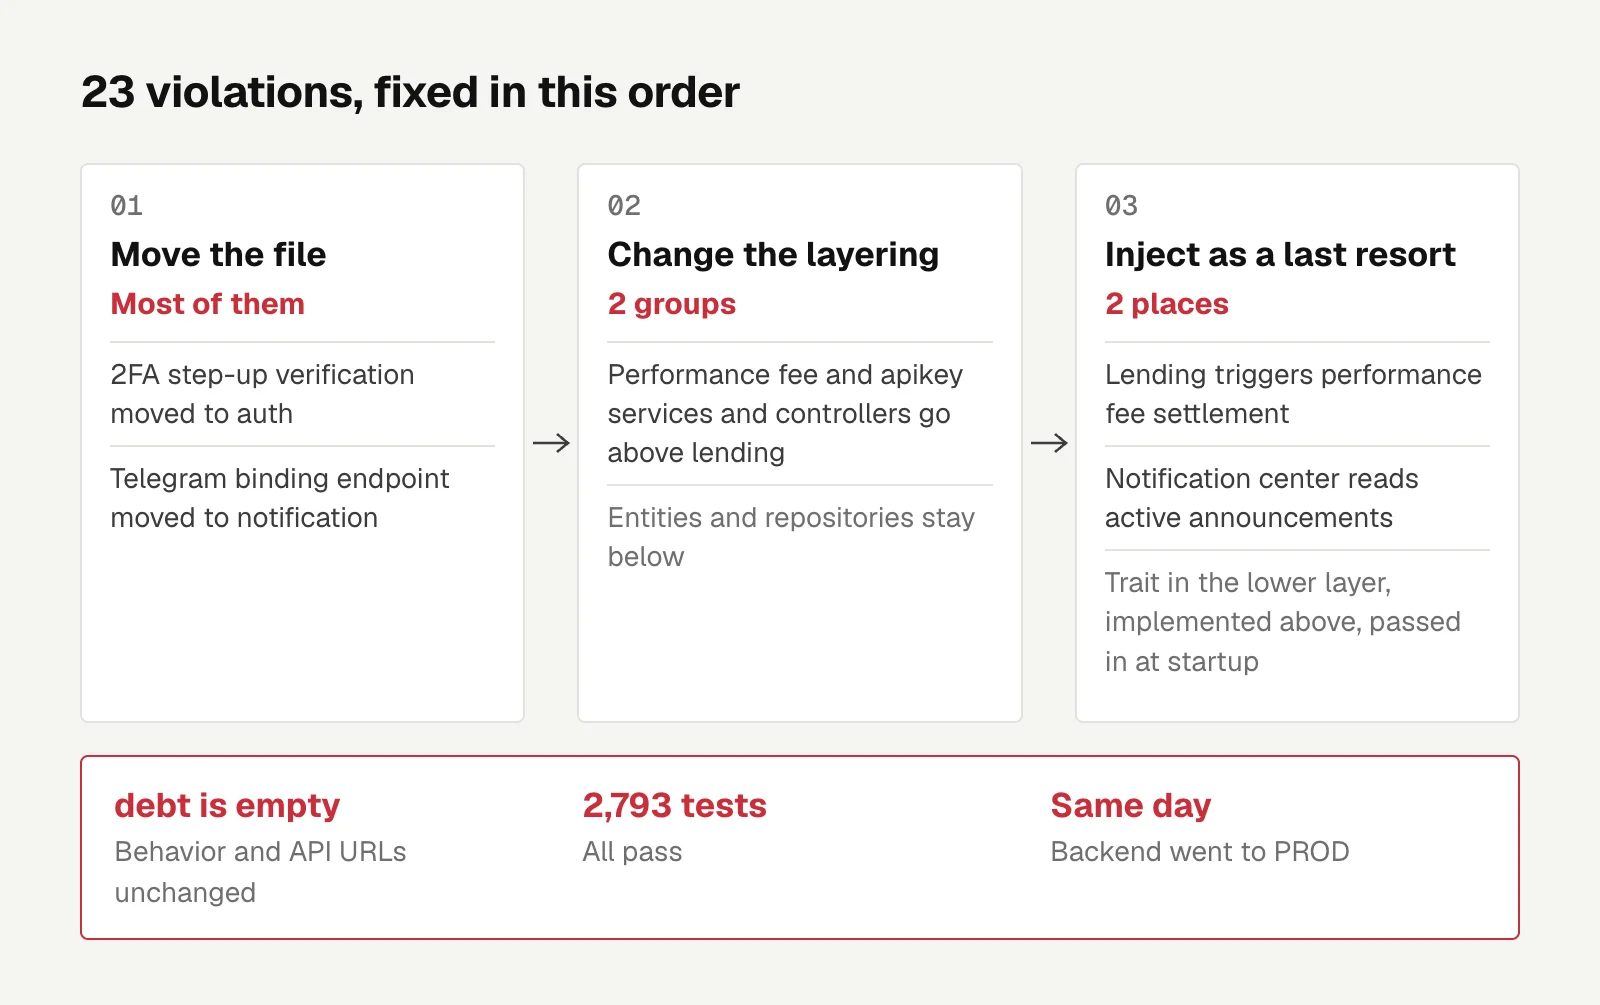
I tried fixes in this order: move the file first, change the layering if that doesn't work, and inject only as a last resort.
Most were files sitting in the wrong layer, and moving them was enough. 2FA step-up verification moved to auth, for instance, and the Telegram binding endpoint moved to notification.
Two groups were cases where the layers had been drawn too coarsely. The performance fee and apikey services and controllers genuinely need to read and write lending data, so they went above lending, while their entities and repositories stayed below.
Only 2 places really needed injection: lending triggering performance fee settlement, and the notification center reading active announcements. In both cases the two sides genuinely need each other.
The fix is plain dependency injection. The lower layer defines a trait, the upper layer implements it, and the implementation gets passed in at startup.
Injection comes last because once it's in place, the lower-layer code no longer shows who it's actually calling, and anyone reading it has to jump one more hop.
After the cleanup, debt is empty. Behavior and API URLs are unchanged, all 2,793 tests pass, and the backend went to PROD the same day.
Blind spots: pub use and macros
The scanner doesn't understand semantics.
Items re-exported through pub use are only attributed to the file that re-exports them. Paths that only appear after macro expansion aren't recognized at all.
That's the cost of skipping compilation. Keep these two blind spots in mind when reading the rules and the map.
Tools
Claude Code Mods From a Month of Session Logs: Five Bands, Status Line Items, and Commands
I had Claude read a month of session logs for requests I kept repeating and turned them into bands, status line items, and commands; the most useful, leftovers, tracks what Claude leaves behind.
Letters
Loading comments…