Engineering · 2026.10.03 · 5 min · Updated 2026.10.26
High Coverage, Still Missing Tests? Using the CRAP Metric to Find the Functions That Need Them Most
With mostly agent-written code, high line coverage couldn't show whether the gaps sat in the most complex functions; a CRAP threshold of 8 cleared 200-plus offending functions and turned up 72 issues to fix.
Reading
High line coverage can't tell you whether the few untested lines that remain happen to sit in your most complex functions.
Most of the code in my Rust and React project was written by agents, and overall line coverage is high. After adopting the CRAP metric, it turned out the untested lines did sit there. On the backend, even a loose threshold caught functions like the scheduler with untested branches, and on the frontend the request pipeline had no tests at all.
The threshold ended up at 8, and both frontend and backend were cleared to 0 functions over it. Along the way I fixed 72 issues found while reading the code.
What CRAP measures
CRAP (Change Risk Anti-Patterns) gives each function a score:
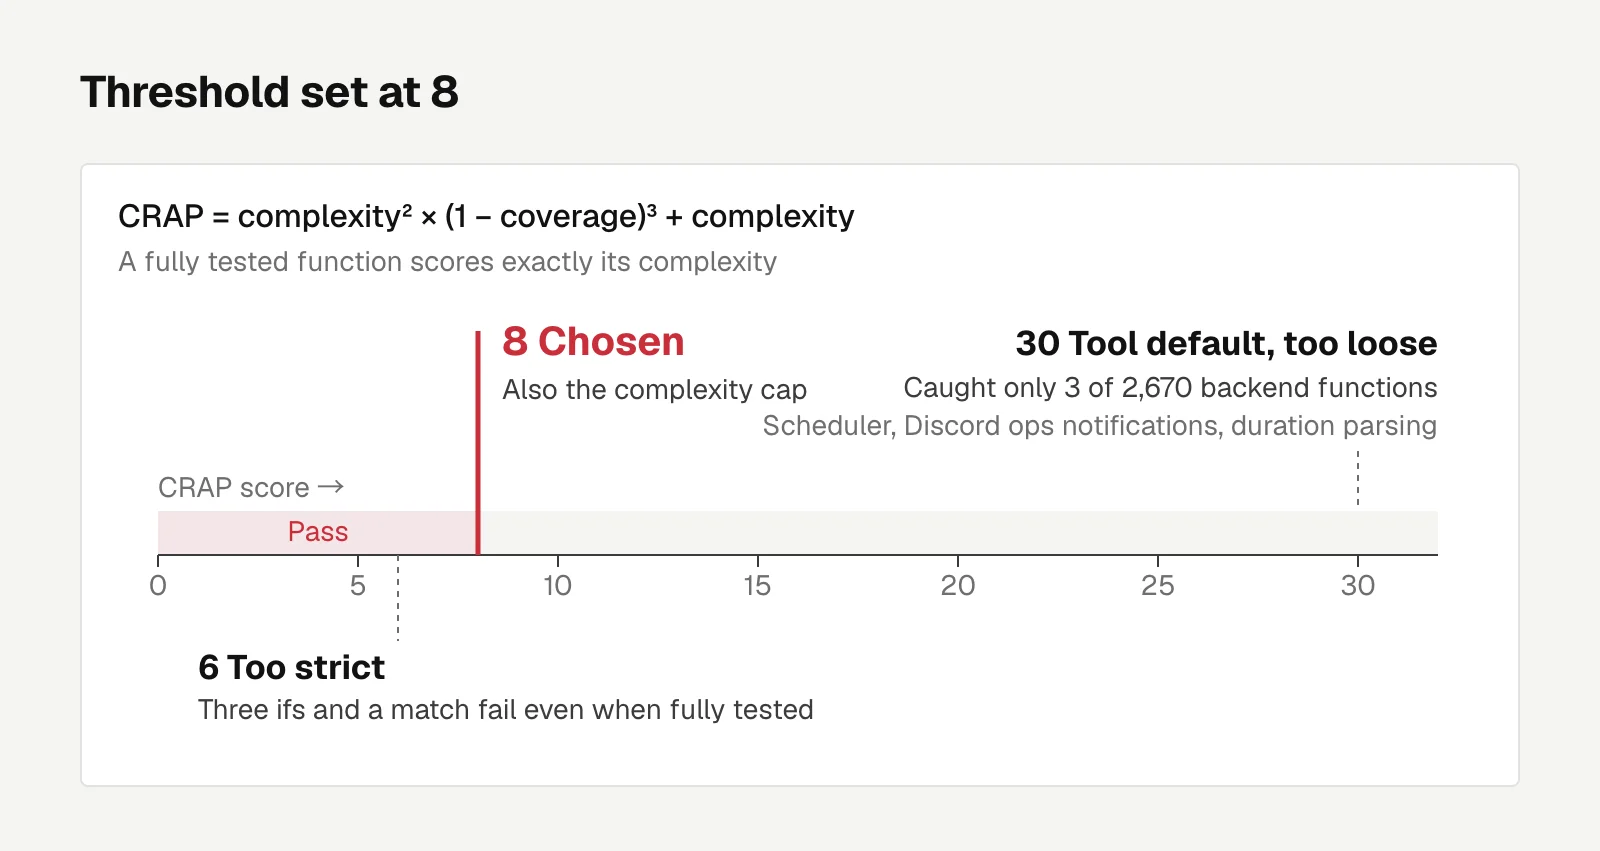
CRAP = complexity² × (1 − coverage)³ + complexity
Complexity here is cyclomatic complexity, the number of independent paths through a function. More branches, higher number.
Lots of branches with no tests means a high score. A fully tested function scores exactly its complexity.
What I wanted was a list pointing at which functions need tests or need splitting, plus a check at PR time. The backend uses the off-the-shelf cargo-crap together with cargo-llvm-cov, and the frontend followed the next day.
Threshold 8, changed files only
I started with the tool's default of 30, and across all 2,670 backend functions it caught only 3: the scheduler, the Discord ops notifications, and duration parsing.
All three really did have untested branches. 30 was just too loose for this codebase.
Those three, plus the untested frontend request pipeline, all went unnoticed while line coverage looked high. CRAP put them at the top of the list, which gave me a basis for deciding what to test first.
At 6, a function with three ifs and a match can't pass even when fully tested, so I settled on 8. Since a fully tested function scores its complexity, 8 also works as the complexity cap.
Rust's ? operator returns early with the error. By default, cargo-crap adds 1 for every ?, but line coverage can't measure the path where the error propagates up.
Counting them means a function with a long chain of DB calls still scores high when fully tested, and the checkout function's complexity would jump from 7 to 21. So I configured ? not to count as a branch.
The PR rule is that changed files can't contain functions over the threshold, and unchanged files aren't checked.
That way there's no need for a baseline (a snapshot of existing violations), and existing offenders don't block unrelated PRs.
I didn't go with failing whenever any function in the repo exceeds the threshold. As long as a single one remained on main, every PR would be red.
The backend check runs as its own job and isn't triggered by PRs that don't touch the backend. It isn't a GitHub required status check, because then every PR would have to report it and burn an extra minute of quota.
Instead, the merge script enforces it. Details are in guarding main with a merge script and a deploy preflight.
Scoring the frontend on the TypeScript AST
Before this, the frontend had only 8 Playwright tests and no unit tests.
My rule is that ?. and ?? don't count as branches. Neither the off-the-shelf crap4ts nor ESLint's complexity rule has a setting to turn that off, so I wrote the scoring script myself on top of the TypeScript AST.
Coverage has to include branch exits: both sides of an if or a ternary, and every operand of && and ||, have to be exercised before a function counts as fully tested.
Frontend branches mostly live inside a single statement, like JSX's {cond && …}. If you only count lines, a component hits 100% after rendering once, and the score means nothing.
For coverage I used Vitest's istanbul provider, because in my tests v8 counted lines after an early return as executed even though they never ran.
Cleaning up 200-plus functions
The moment the threshold dropped to 8, 120 backend functions and 88 frontend functions were over it.
For the transition I kept a cleanup list. Files on the list temporarily kept the old threshold, every other file was held to 8 immediately, and each file came off the list once it was cleaned. Wherever the work stopped, nothing already cleaned could slide back.
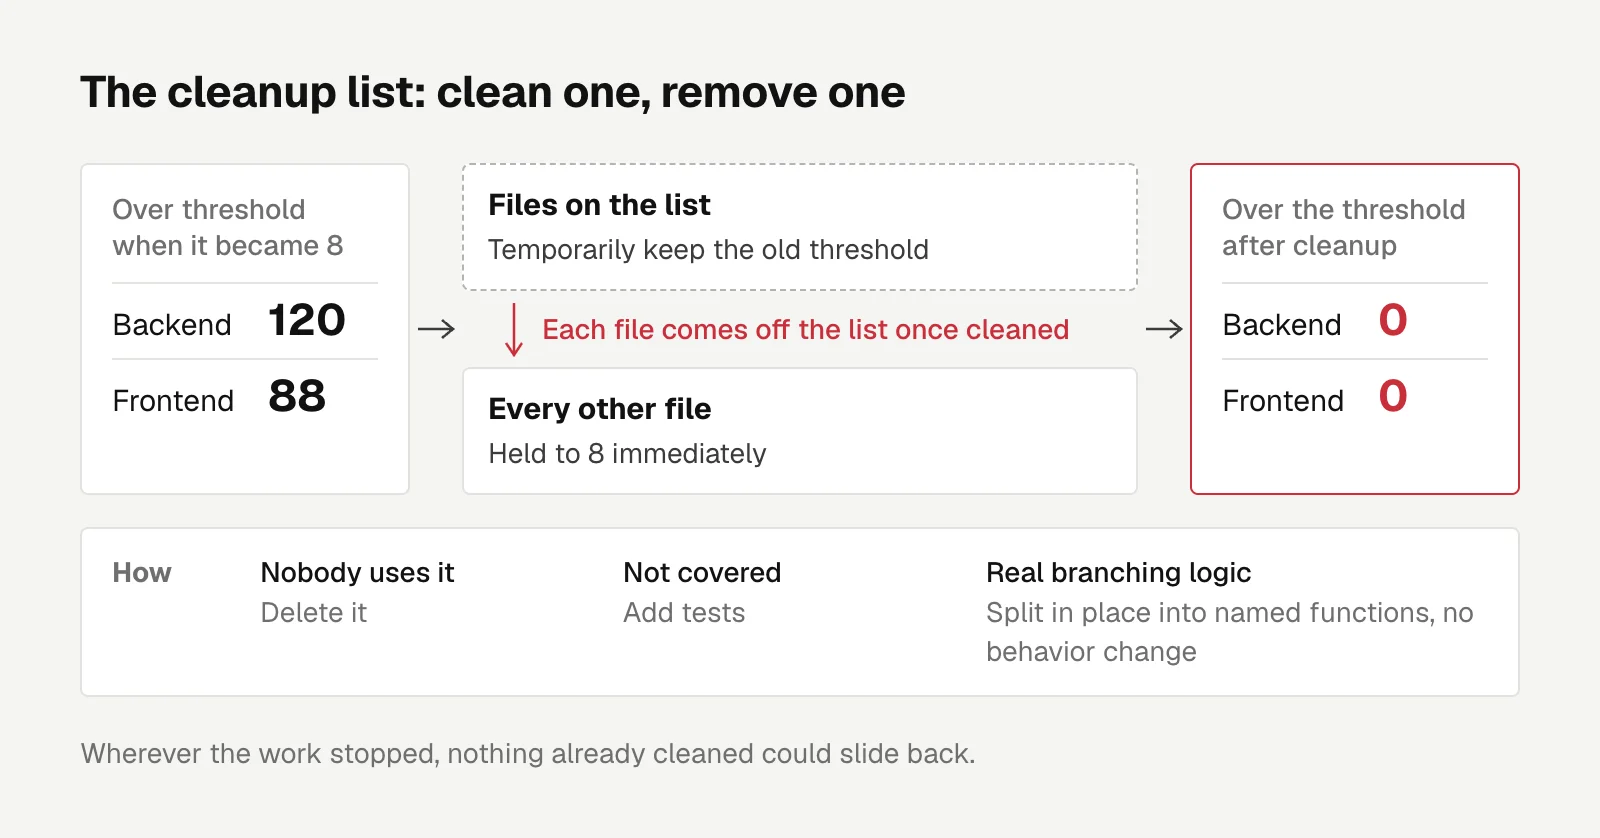
The principles: delete what nobody uses, add tests for what isn't covered, and only split functions with real branching logic. Splitting meant moving that logic in place into named functions without changing behavior.
Before splitting a frontend page, I first wrote tests against the original page until they all passed. After the split I compared every DOM state, plus the order of API and navigation calls, across 966 scenarios in total.
That comparison really did catch a bad split. After extracting a block with an await into a new async function, an API call and a navigation swapped order.
Problems found while reading code to write tests were filed as separate issues and fixed. For example:
- New-login notifications labeled iPhones and iPads as macOS, because the OS check matched the
Mac OS Xstring first - The duplicate-registration check used the email without lowercasing it, so a repeat signup with different casing returned 500
- The reason users picked when pausing the bot only lived on the screen and was never actually sent
The cost: tests and CI time
Test counts and frontend CI time, before and after:
| Item | Before | After |
|---|---|---|
| Backend tests | 2,655 | 2,767 |
| Frontend tests | 0 | 2,604 |
| Frontend CI checks | under a minute | 1 min 47 s |
That's an extra minute of quota on every frontend PR.
Engineering
Catching Dependency Cycles in Rust and TypeScript: A Homemade Module Scanner With Layering Rules in CI
My 18 backend packages had several dependency cycles tracked only by memory, so I wrote a compile-free scanner for a clickable architecture map and CI layering rules, then cleared 23 violations in one day.
Letters
Loading comments…